
spd_learn.models.MAtt#
- class spd_learn.models.MAtt(n_patches: int = 2, n_chans: int = 22, n_outputs: int = 4, temporal_out_channels: int = 20, temporal_kernel_size: int = 12, temporal_padding: int = 6, attention_in_features: int = 20, attention_out_features: int = 18, covariance_method=<function sample_covariance>)[source]#
Bases:
ModuleManifold Attention Network for EEG Decoding (MAtt).
This class implements the MAtt model [Pan et al., 2022], a manifold attention network for EEG decoding. The architecture integrates Riemannian geometry with attention mechanisms on the manifold of SPD matrices.
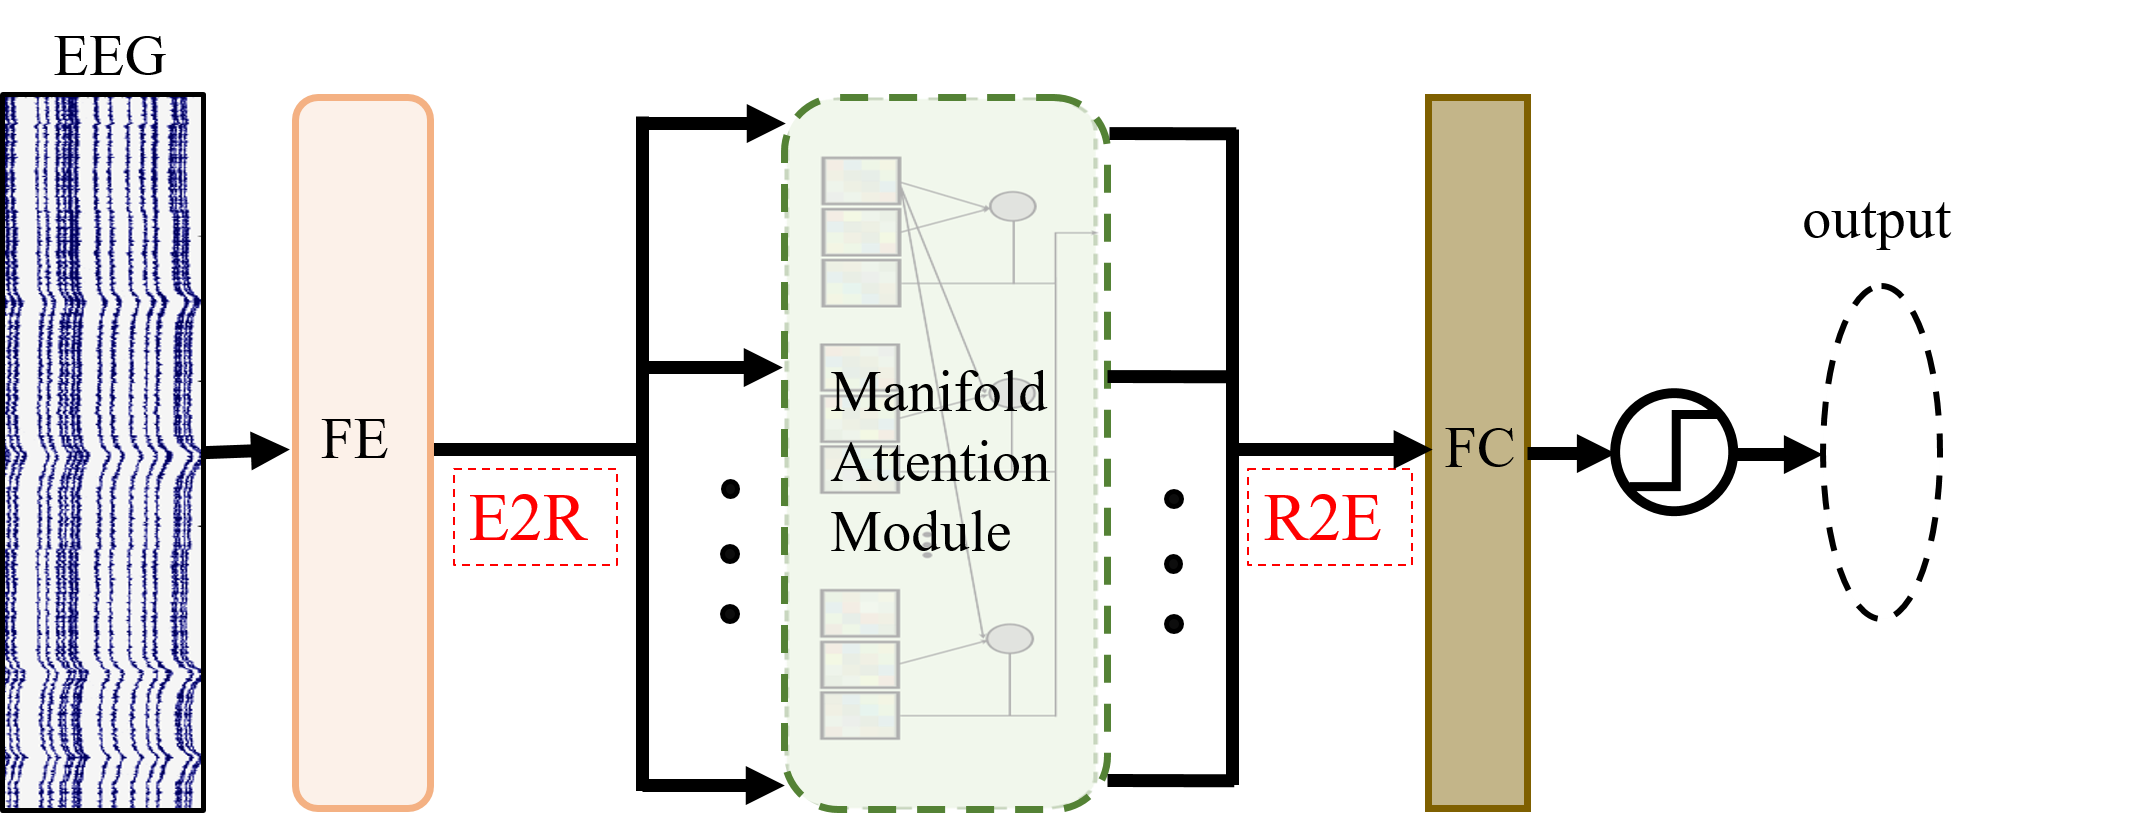
The model consists of the following stages:
Feature Extraction: Raw EEG signals are processed by two convolutional layers with batch normalization to extract spatial and spatiotemporal features.
Euclidean-to-Riemannian (E2R) Mapping: The extracted features are segmented into patches, and a sample covariance matrix is computed for each patch to create SPD data points.
Manifold Attention Module: An attention mechanism is applied to the SPD matrices, using bilinear mappings and the Log-Euclidean distance to compute attention scores.
Riemannian-to-Euclidean (R2E) Mapping: A ReEig layer and a Log-Euclidean mapping project the SPD data back to a Euclidean space.
Classification: A fully connected linear layer outputs the final class scores.
- Parameters:
n_patches (int, default=2) – Number of patches for the time dimension.
n_chans (int, default=22) – Number of output channels for the first convolutional layer.
n_outputs (int, default=4) – Number of classes for classification.
temporal_out_channels (int, default=20) – Number of output channels for the second convolutional layer.
temporal_kernel_size (int, default=12) – Kernel size for the second convolutional layer.
temporal_padding (int, default=6) – Padding for the second convolutional layer.
attention_in_features (int, default=20) – Input feature dimension for the manifold attention module.
attention_out_features (int, default=18) – Output feature dimension for the manifold attention module.
covariance_method (callable, default=sample_covariance) – The method to use for computing covariance matrices.
- forward(input: Tensor) Tensor[source]#
Forward pass of the MAtt model.
- Parameters:
input (torch.Tensor) – Input tensor of shape (batch_size, n_chans, n_times).
- Returns:
Output tensor of shape (batch_size, n_outputs).
- Return type: